Need Different Solutions?
For any problem with development or anything related to service connect with us
Deploy high-speed, enterprise-grade AI. We transform custom models, LLMs, and intelligent agents into low-latency, multi-region production services that integrate seamlessly with your infrastructure.
Designing an algorithm in a notebook is only the first phase. Running that model inside live, enterprise software requires serious cloud engineering, bulletproof security, low-latency API connections, and continuous uptime. Without robust infrastructure wrapping around the code, even breakthrough applications crash when exposed to real-world operational stress.
Connecting experimental code to everyday business tools takes systematic engineering. Developers have to manage memory footprints, secure private data feeds, isolate system dependencies, and balance GPU hardware costs so that incoming user activity runs smoothly.
Our AI deployment services take that burden off your internal teams. We build production-ready delivery networks so your models process data instantly, allowing your developers to focus on core features rather than patching servers.
Testing environments almost never reflect what happens in the wild. Once real employees or customers start using an app, traffic surges without warning, causing backlogged request queues, sluggish response times, and broken downstream workflows.
The knee-jerk reaction is usually to throw bigger compute instances at the problem, which inflates your monthly cloud bill without fixing the underlying bottleneck. Other teams stick with default container setups that choke the moment concurrent usage spikes.
We solve performance issues at the architectural level instead of just paying for extra hardware. By compiling model weights specifically for your target chips, setting up dynamic micro-batching, and configuring elastic compute clusters, we keep inference fast and responsive without letting your hosting expenses spiral out of control.
Deploy reliable, high-speed AI applications through tailored services designed to match your technical stack, compliance requirements, and operational growth.
Standard web frameworks fall short when handling concurrent data streams. We build specialized serving nodes using model compilation, FP16/INT8 quantization, and intelligent request batching. These techniques squeeze maximum performance out of GPUs and accelerators, cutting execution delays to milliseconds.
Isolated models quickly turn into data silos. Our deployment team builds encrypted microservices, custom middleware, and secure API gateways to keep data moving safely across your business. Whether you’re connecting models to your ERP, primary databases, or internal dashboards, we deliver seamless AI deployment that integrates safely into your software with strict identity management.
Centralized server setups slow down remote users and global teams. We specialize in building enterprise AI customer service solutions global multi-region deployments with dynamic traffic routing. Virtual assistants and customer support tools hit the closest regional server automatically, ensuring instant response times while fulfilling localized data residency compliance.
Running generative models in production without guardrails is a quick path to data leaks, unexpected API bills, and output risks. We build automated PII redactors, token caps, safety filters, and payload validators directly into your pipeline, ensuring your applications stay secure, predictable, and fully compliant.
Generic hosting platforms rarely align with strict enterprise security policies or specialized hardware setups. We design custom deployment architectures tailored around your specific network protocols, uptime SLAs, and infrastructure preferences, giving you full operational control without locking you into a proprietary platform.
Production software shouldn’t drop offline just because you’re pushing a model update, resizing server clusters, or rotating access keys. Users expect steady uptime, whether you’re handling regular maintenance or catching a sudden spike in traffic.
We build deployment pipelines with isolated staging environments, load tests, and zero-downtime release strategies. That way, your team can roll out fresh model weights in the background and fall back on instant rollbacks if an edge case pops up.
An enterprise virtual assistant drops connections during high-volume shifts. An automated document scanner queues incoming files for hours. A scoring system fails because a third-party software API changed its data format. The underlying logic wasn’t the issue, the delivery framework simply couldn’t handle live operations.
Our deployment services bridge that structural gap. By uniting hardware-level optimizations with adaptive load distribution, your software provides dependable results regardless of sudden user spikes.
Scrapping a working codebase just to add AI features is a quick way to burn an engineering budget. The tech you rely on daily should stay in place, new models should fit into your existing stack, not force a complete rewrite.
We engineer deployment layers that drop right into your running setup. Your databases, auth setups, and internal tools stay as they are, while our infrastructure handles the heavy model processing quietly in the background.
Unseen memory leaks, server bottlenecks, and connection drops are difficult to trace without dedicated monitoring. An API endpoint might look active on paper while background queues stall, quietly backing up tasks across your organization.
We embed real-time observability tools that monitor GPU health, memory consumption, concurrency levels, and execution speeds. If performance drops below established targets, the platform spins up extra computing nodes or notifies your engineering leads instantly.
Automating your build pipeline shouldn’t mean losing sight of what’s running. In tightly regulated fields like healthcare, finance, or logistics, engineering leads need clear system logs, reliable audit trails, and hard-stop controls they can trigger in seconds.
We set up deployment architecture with simple central management layers and grounded governance tools. That gives your ops team direct, live visibility over system health, API traffic, and monthly hosting spend, plus quick controls to update access policies or halt specific endpoints whenever requirements change.
Low-latency financial feeds and nightly batch jobs don’t run on the same architecture. Your data volume, compliance requirements, and execution speed dictate the build, not a template.
We look directly at your active pipelines, map out where bottlenecks hide, and pinpoint hardware constraints early. Then we assemble a deployment setup tuned around your actual traffic patterns and system dependencies.
Static setups eventually hit a ceiling when user demand grows. Some organizations need to resolve performance lags on customer-facing platforms, others want to automate model rollouts, while many simply need infrastructure that scales smoothly as the business expands.
If you are ready to move your models out of development and into a secure, production-grade environment, we are here to help.
Reach out to the engineering team at Amenity Technologies to review your software stack, discuss technical goals, and map out a practical path to production deployment.
As an emerging Gen AI development company, our expertise spans a diverse range of models that help you in achieving new levels of creativity, efficiency, and intelligence.
ChatGPT
Claude
Gemini
Llama
DeepSeek
Qwen
FLUX
Stable Diffusion XL (SDXL)
Whisper
ElevenLabs
Addressing Unique Problems with Advanced Gen AI Solutions.
500+
AI Projects Delivered Across Industries
100+
Generative AI Models Mastered
200+
Global Clients Empowered
5x
Faster Deployment Expertise
99.9%
Client Satisfaction Rate
30
Served with Scalable AI Services
Trusted by 2,000+ Brands
Read our case studies, which showcase our experience and strategy for implementing different Gen AI models into business workflows successfully.
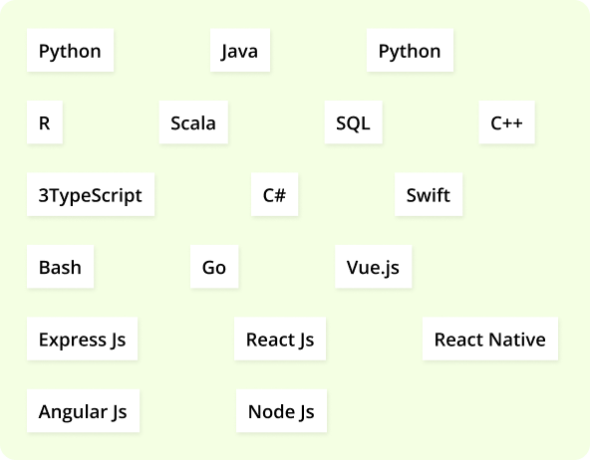
At Amenity Tech, we have a pre-vetted pool of talented developers with expertise and hands-on
experience in a range of technologies.
Create dynamic web apps using reusable components with React.
Develop structured, scalable front-end apps with Angular.
Lightweight, fast, and flexible interfaces built with Vue.js.
Create interactive, responsive websites using core JavaScript skills.
Design clean, responsive layouts using HTML5 and CSS3.
Build fast and flexible apps or data tools with Python
Develop modern web apps using Laravel’s PHP framework.
Create real-time, high-performance apps with Node.js.
Secure, scalable back-ends built with Django and Python.
Build sleek iOS apps with Swift and Apple-native tools.
Create reliable Android apps for all devices and versions.
Cross-platform apps from a single codebase with Flutter.
Build native-like mobile apps with shared React code.
Integrate smart, AI-powered features into your app.
Deploy AI chat solutions using OpenAI’s ChatGPT.
Design and train deep learning models with PyTorch.
Optimize AI outputs with expert-crafted prompts.
Extract insights from complex data with AI and ML.
Visualize and interpret data to guide business decisions.
Build scalable pipelines and manage data infrastructure.
Testimonials
Read what our clients have to say about the Amenity Tech partnership and the benefits they have received from our innovative Gen AI solutions.
The Amenity Team is a standout group of professionals in AI chatbot development, consistently delivering bug-free, expert-level code. Their strong communication skills and seamless collaboration make working with them a breeze. With deep expertise in AI chatbot projects using LLMs and ChatGPT, including web and WhatsApp platforms, you’re in the best hands!
Ganesh Tangella
Have the honor and privilege of working with Amenity on many projects these last 6 months. Amenity has demonstrated immense and exceptional capabilities in developing robust custom computer-vision-learning algorithms, Deep Neural Networks, and Convolutional Neural Networks, and has advanced our R&D exponentially! Trust can never be more valuable and critical for any startup, especially when building and developing partnerships!
I must thank Amenity for opening our eyes and expanding our AI capabilities beyond measure!
Charles B. Moss II
Excellent work, Great communication throughout the project. Took time to understand the task then provided an excellent out come.
Hanif-jan-mohamed
Dealing with amenity such good experience on our AI project. Very co operative team with polite nature.
Aarohi Kaur
Excellent work, Great communication throughout the project. Amenity delivered one of our Most Difficult NLP Based project.
Daniel Sommer
Excellent Work Experience with Amenity, completed incredible IoT work for our project.
Harnam Singh Thakur
Dealing with Amenity such Good Experience on Project. They work are Accurate According to Requirements Also Team is very co operative and Trustworthy.
Naif
How will Generative AI help my business?
Generative AI models are capable of producing new content, such as text, images, audio, code, or synthetic data, based on patterns learned from large datasets. Gen AI powers intelligent chatbots for customer support, marketing content generation, personalised product recommendations, document summarisation, and synthetic training data creation.
What type of Gen AI models do you specialise in?
We specialise in deploying a range of Gen AI models:
Can you fine-tune OpenAI models, such as GPT-4, according to industry-specific needs?
While OpenAI does not currently allow full fine-tuning of GPT-4, we implement advanced prompt engineering, embedding-based retrieval (RAG), and custom context injection techniques to make ChatGPT responses highly relevant to your domain. For open-source models, such as LLaMA 2, Mistral, or Falcon, we can easily fine-tune them.
What is the process of Gen AI implementation?
Our end-to-end Gen AI implementation includes:
How do you ensure data privacy and model compliance?
We follow strict enterprise-grade security practices and adhere to frameworks such as GDPR, CCPA, and HIPAA, where applicable. All training data is encrypted in transit and at rest, and we employ differential privacy, anonymisation, and access control policies.
Can you integrate Gen AI with our existing applications or workflows?
Yes. We offer API-based and SDK-based integration of Gen AI models with your existing applications (e.g., CRMs, chat platforms, ERPs), data sources, and other internal tools, such as Slack, Salesforce, and Shopify.